Webpage Metadata Extractor
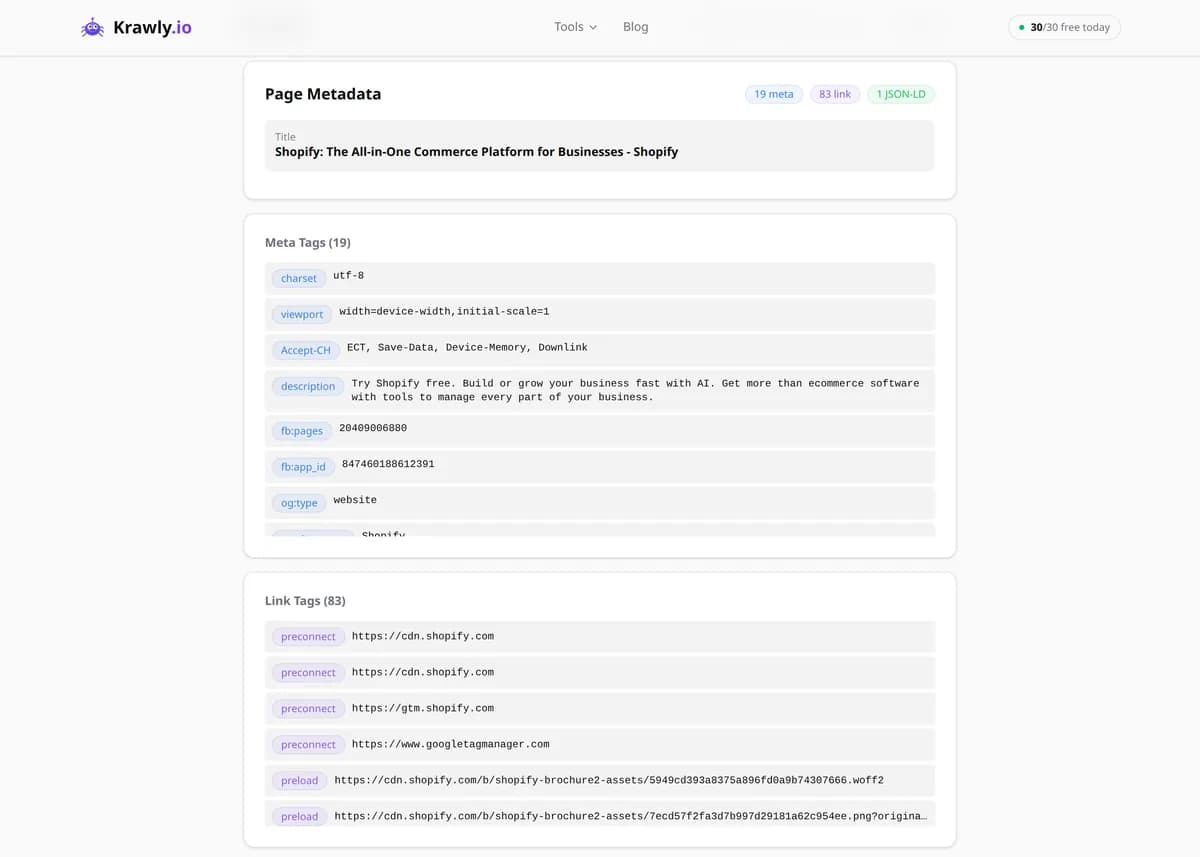
Extract all meta tags, link tags, JSON-LD, and head section data from a webpage.
Explore More Free Tools
Discover 63 free public tools for web scraping, SEO analysis, OSINT, and more. 30 free uses every day — no signup required.
What is Webpage Metadata Extractor?
Webpage Metadata Extractor pulls all data from a page's HEAD section including meta tags (name, property, http-equiv), link tags (stylesheets, canonical, hreflang), and JSON-LD structured data.
Use cases
- Full metadata audit
- Check Open Graph tags
- Find charset and language
- Extract all link relations
Key features
Frequently asked questions
Title, meta description, canonical, robots, Open Graph tags, and structured data (JSON-LD) are the most important metadata elements for SEO.
You might also like
Related tools & similar free utilities
Lead Finder
Find emails, phone numbers, and social media links from any website.
Tables
Extract HTML tables from any webpage and download as CSV/Excel.
Sitemap
Find and extract all URLs from a website's sitemap.xml.
Content
Extract clean article text, metadata, and images from any webpage.
SEO Check
Analyze SEO metadata, Open Graph, headings, content metrics and get a score.
Link Checker
Crawl any webpage and check all links for broken URLs, redirects, timeouts, and errors.
Looking for something specific? Browse all 63 Krawly tools